
ASRock Intel Arc Pro B60 Creator 24GB
3.9Editor score
24GB GDDR6 Memory
456 GB/s Bandwidth
Optimized Multi-GPU Linux
This guide compares the top 10 GPUs for Llm inference and training, covering consumer and workstation cards to help you choose the right hardware.
Selecting the right GPU for Llm workloads is critical for balancing performance, memory capacity, and cost. As AI models grow larger, hardware requirements become more demanding for local deployment.
We evaluated ten top GPUs based on memory bandwidth, architecture efficiency, and multi-GPU scaling capabilities. Our analysis covers consumer gaming cards and professional workstation accelerators.
Each pick highlights key specs and ideal use cases to simplify your decision. Prices fluctuate frequently, so verify current listings before purchasing to ensure you get the best value.
3.9Editor score

3.6Editor score

4.3Editor score
The following table provides a side-by-side comparison of all ten GPUs reviewed in this guide, highlighting their core specifications and ideal deployment scenarios.




The GIGABYTE GeForce RTX 5080 stands out as the top choice for local Llm inference. With 16GB of next-gen GDDR7 memory, it delivers exceptional bandwidth for handling medium-sized models efficiently.
We may earn a commission when you buy through this link, at no additional cost to you.
Powered by the NVIDIA Blackwell architecture, this card includes DLSS 4 and advanced tensor cores. Its WINDFORCE cooling system ensures stable clock speeds during prolonged AI workloads without throttling.
While expensive, the performance per watt justifies the cost for serious developers. The PCIe 5.0 interface ensures future-proof connectivity, making it a solid long-term investment for AI pipelines.
Developers seeking high-speed inference on consumer hardware should prioritize this card. It balances raw compute power with thermal management better than most competing options in its class.
The 256-bit GDDR7 interface provides critical speed for token generation. This reduces latency when running 7B to 13B parameter models locally without offloading.
WINDFORCE fans utilize server-grade thermal gel to dissipate heat effectively. This design prevents overheating during sustained AI training or inference sessions.
We may earn a commission when you buy through this link, at no additional cost to you.
ASRock's Intel Arc Pro B60 offers massive 24GB VRAM at a budget-friendly price. This memory capacity is crucial for running larger models or batch processing inference tasks on limited hardware.
We may earn a commission when you buy through this link, at no additional cost to you.
Built on Intel's Xe2-HPG architecture, it provides 197 INT8 TOPS of AI acceleration. The card is explicitly optimized for Linux multi-GPU deployments, making it ideal for home server clusters.
The blower-style cooling is compact but can be loud under load. However, the low TDP of 200W ensures it runs cool enough for dense rack configurations without excessive electricity costs.
For hobbyists needing high capacity without enterprise costs, this card is a strong contender. It excels in scenarios where VRAM size matters more than raw single-card compute speed.
Optimized for Linux environments, allowing users to link multiple cards for expanded memory pools. This is vital for training or running large context window models locally.
The 456 GB/s bandwidth ensures data moves quickly between memory and cores. This reduces bottlenecks during inference, keeping response times acceptable even with 24GB loads.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASRock Radeon AI PRO R9700 brings 32GB of GDDR6 memory to the professional workstation market. This extra headroom allows for significantly larger context windows without compromising model precision.
We may earn a commission when you buy through this link, at no additional cost to you.
Its RDNA 4 architecture includes dedicated AI accelerators for optimized performance. The vapor chamber heatsink and industrial thermal interface material ensure reliability during continuous training cycles.
While pricier than consumer cards, the build quality supports 24/7 operation. Professional drivers are validated for stability, which is critical for enterprise environments where downtime is unacceptable.
Teams requiring high capacity and stability should consider this professional solution. It bridges the gap between consumer gaming hardware and expensive data center accelerators effectively.
Vapor chamber and PTM7950 materials prevent thermal throttling. This is essential for maintaining peak clock speeds during long LLM fine-tuning sessions.
ISV certified drivers ensure compatibility with industry AI software. This reduces compatibility issues when deploying models on enterprise Linux systems.
We may earn a commission when you buy through this link, at no additional cost to you.
GIGABYTE's RX 9070 XT provides a robust 16GB VRAM solution for mid-range setups. While designed primarily for gaming, its memory bandwidth supports basic LLM inference tasks competently.
We may earn a commission when you buy through this link, at no additional cost to you.
The WINDFORCE cooling system with Hawk fans and server-grade thermal gel maintains cool temperatures. This stability is beneficial for running models that do not require massive multi-GPU scaling.
AMD's AI acceleration is improving but lags slightly behind NVIDIA. However, for users already invested in AMD ecosystems, this card offers a balance of visual and computational power.
Gamers who also want basic AI capabilities might find this card appealing. It serves as a versatile entry point into local inference without requiring a dedicated workstation.
Server-grade thermal conductive gel improves heat transfer to heatsinks. This helps keep temperatures low during extended periods of active processing.
Support for the latest PCIe 5.0 standard ensures high data transfer rates. This prepares the system for future CPUs that leverage higher bandwidths.
We may earn a commission when you buy through this link, at no additional cost to you.
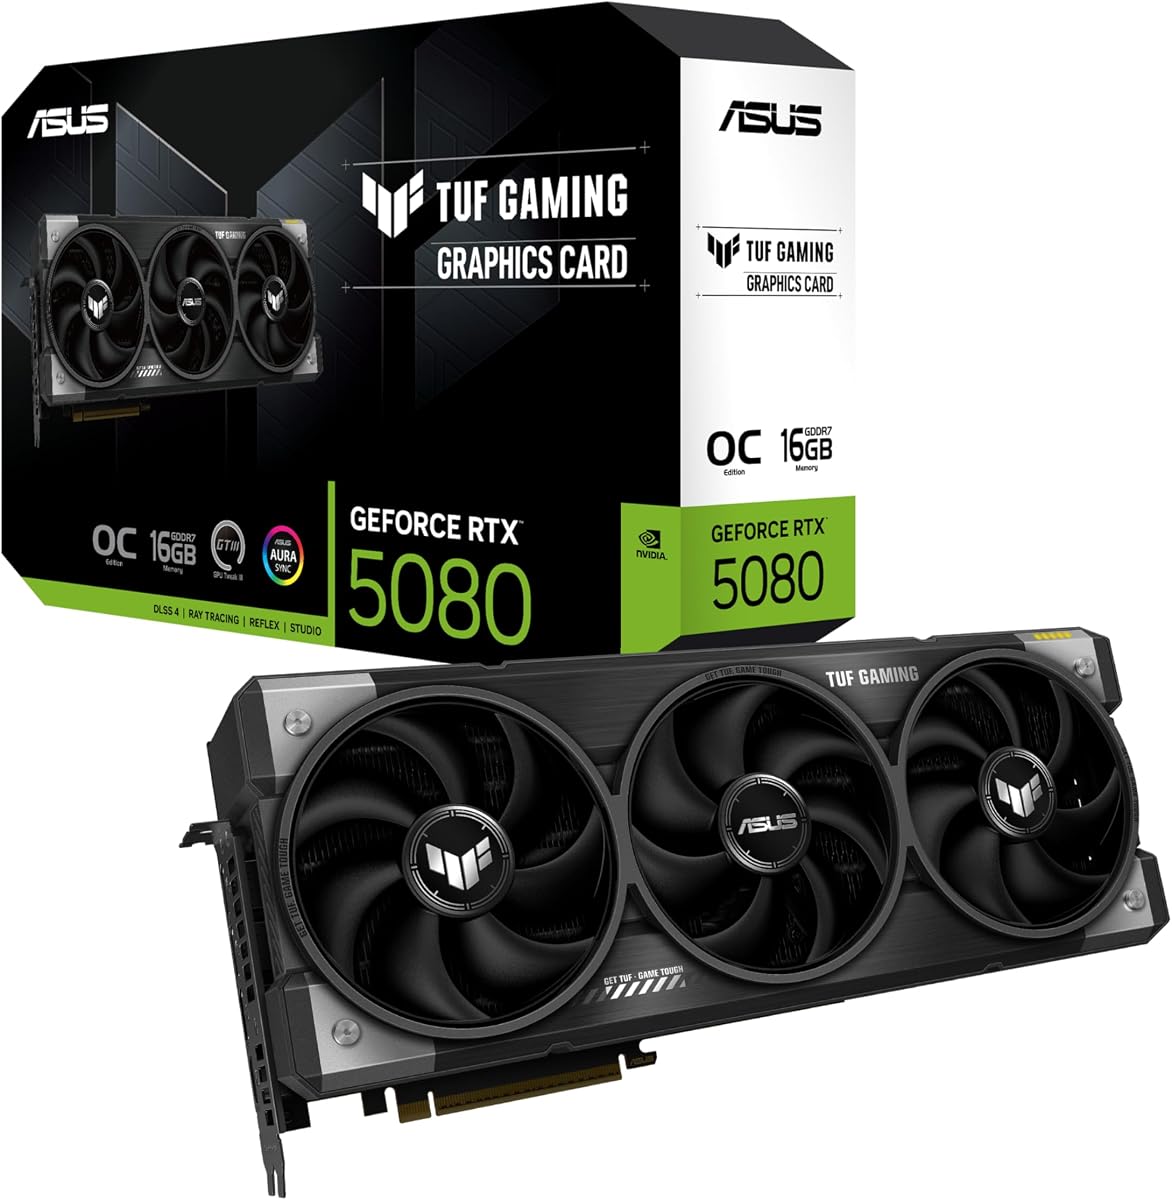
The ASUS TUF RTX 5080 focuses on long-term durability for intensive workloads. Its military-grade components and phase-change thermal pads ensure consistent performance over years of usage.
We may earn a commission when you buy through this link, at no additional cost to you.
With 16GB GDDR7 memory, it handles inference tasks quickly. The Auto-Extreme automated manufacturing process reduces the risk of defects, adding reliability for critical AI development.
However, the 3.6-slot design requires significant case clearance. Users must verify their chassis can accommodate the length and width before purchasing this robust card.
Those valuing build quality and longevity should prioritize this model. It offers peace of mind for users running complex models that stress hardware continuously.
Thermal pads outlast traditional paste, maintaining efficiency over time. This is vital for reducing maintenance needs in always-on inference servers.
Protective coating guards against moisture and dust. This adds resilience against environmental factors that could degrade performance.
We may earn a commission when you buy through this link, at no additional cost to you.
ASUS Turbo Radeon AI PRO R9700 is explicitly built for running LLMs locally. Its 32GB GDDR6 memory ensures large models run smoothly without offloading to system RAM.
We may earn a commission when you buy through this link, at no additional cost to you.
The wave-pattern shroud cuts memory temperatures significantly. This helps maintain steady clock speeds during long training runs, preventing thermal throttling that slows down processing.
While it offers 128 AI accelerators for fast inference, software maturity is a consideration. Users must ensure their stack supports AMD RDNA 4 acceleration efficiently.
Local AI cluster builders will appreciate the multi-GPU support. It allows for scaling compute power across multiple cards effectively for heavy inference workloads.
Wave-pattern design reduces memory temperature by up to 16%. This keeps performance stable during extended AI tasks without overheating.
Dual ball fan bearings are rated twice as long as sleeve types. This reduces maintenance needs for 24/7 operation setups.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASUS Dual RTX 5060 Ti offers a compact form factor ideal for small chassis. Despite its size, it delivers 16GB GDDR7 memory, enabling decent performance for smaller language models.
We may earn a commission when you buy through this link, at no additional cost to you.
Its Axial-tech fan design provides downward air pressure efficiently. The 0dB technology ensures silent operation during light loads, making it suitable for office environments.
While slower than higher-end models, it balances performance with physical size. The dual BIOS feature lets users toggle between performance and quiet profiles easily.
Users with limited case space but high VRAM needs should consider this. It proves that small form factors can still handle meaningful AI tasks effectively.
2.5-slot design maximizes compatibility in tight spaces. This makes it ideal for compact builds needing AI acceleration.
767 AI TOPS delivers strong inference speed for its class. This is sufficient for most standard LLM applications.
We may earn a commission when you buy through this link, at no additional cost to you.
Tesla L40S provides 48GB of VRAM designed specifically for AI and HPC workloads. Its massive memory capacity supports large batch processing and complex generative AI pipelines.
We may earn a commission when you buy through this link, at no additional cost to you.
As a dedicated accelerator, it lacks consumer graphics features like display outputs. Instead, it focuses entirely on raw compute power and throughput for server rack deployments.
Enterprise support ensures stable driver updates and long-term availability. This is critical for businesses that rely on consistent performance without unexpected hardware failures.
Organizations needing heavy-duty inference capabilities should prioritize this accelerator. It offers a reliable solution for scaling AI workloads across data centers.
48GB memory allows running multiple models simultaneously. This improves throughput for high-volume inference tasks.
Designed for rack deployment with optimized cooling. This ensures long-term stability in controlled server environments.
We may earn a commission when you buy through this link, at no additional cost to you.
RTX PRO 6000 Max-Q packs 96GB of ECC GDDR7 memory for unmatched local capacity. It eliminates VRAM bottlenecks, enabling massive context window LLMs to run on single desktops.
We may earn a commission when you buy through this link, at no additional cost to you.
Max-Q design optimizes power to 300W while delivering 3,511 TOPS. This efficiency allows multi-GPU desktop scaling without needing specialized power infrastructure.
ECC memory ensures data accuracy during long inference sessions. For scientific or enterprise use cases, this reliability is critical to prevent subtle calculation errors.
Advanced researchers and data scientists should choose this workstation card. It bridges the gap between desktop convenience and server-grade memory requirements.
96GB memory allows running heavy open-source models locally. This removes dependency on cloud subscriptions for complex tasks.
300W cap enables multiple cards on a single system. This provides high throughput without excessive heat generation.
We may earn a commission when you buy through this link, at no additional cost to you.
RTX PRO 6000 Blackwell delivers 96GB DDR7 ECC for maximum stability. Its 5th Gen Tensor Cores support FP4 precision, reducing memory usage for faster local fine-tuning.
We may earn a commission when you buy through this link, at no additional cost to you.
Universal MIG allows dividing the GPU into isolated instances. This feature secures concurrent workloads, ensuring different users or apps do not interfere with each other.
Double-flow-through cooling sustains peak performance under heavy loads. This design is crucial for maintaining reliability during complex engineering or data science tasks.
Engineering and design teams needing high capacity and isolation should select this card. It provides secure, scalable power for demanding professional workflows.
Support for FP4 reduces memory usage while maintaining accuracy. This enables faster fine-tuning of LLMs locally.
Universal MIG divides resources into secure instances. This ensures safe multi-user workflows on a single physical GPU.
We may earn a commission when you buy through this link, at no additional cost to you.
Selecting the right GPU requires balancing memory capacity, architecture efficiency, and budget constraints.
Video RAM (VRAM) is the most critical factor for running LLMs. Models with billions of parameters require significant memory to load weights and activations without offloading to slower system RAM. Generally, 16GB is a minimum for basic inference, while 24GB or 32GB is recommended for fine-tuning and larger context windows. High-end cards offering 48GB or 96GB provide the flexibility to run massive open-source models locally.
Always prioritize cards with at least 16GB of VRAM for meaningful AI work. If budget allows, aim for 24GB or more to future-proof your setup as models grow larger.
Bandwidth determines how fast data moves between the GPU's memory and its processing cores. Even with high VRAM, slow bandwidth can create bottlenecks that limit token generation speeds. Look for GPUs with DDR7 memory or high-speed DDR6 configurations, as these offer significantly higher transfer rates than older standards. This speed directly impacts the responsiveness of your AI applications.
Aim for GPUs with bandwidth exceeding 500 GB/s to ensure smooth performance. Faster memory prevents the AI from stalling while processing complex queries.
Modern architectures like NVIDIA Blackwell and AMD RDNA 4 include dedicated AI accelerators and tensor cores. These specialized units handle matrix multiplications required by transformers much faster than general compute cores. NVIDIA has traditionally led in software support, but AMD and Intel are closing the gap with optimized drivers for Linux and Python stacks.
Choose a card with the latest generation AI-specific hardware for best efficiency. Newer tensor cores often support mixed-precision formats that reduce memory usage without sacrificing accuracy.
The PCIe interface acts as the bridge between the CPU and GPU. For data-heavy workloads like AI training, PCIe 5.0 offers double the bandwidth of PCIe 4.0, reducing latency during data loading. While consumer GPUs often support PCIe 5.0, workstation cards fully utilize this speed for multi-GPU scaling and high-performance computing tasks.
Verify your motherboard supports PCIe 5.0 to get the most out of modern GPUs. Older systems may bottleneck high-end cards if the bus is too slow.
AI workloads push GPUs to peak power draw for extended periods. Ensure your power supply unit (PSU) can handle the card's wattage requirements. Look for cards with efficient cooling solutions like blower fans or advanced liquid cooling to prevent thermal throttling. Throttling reduces clock speeds and slows down inference significantly.
Select a card with efficient thermal design and a PSU matching or exceeding its TDP. Stable temperatures ensure consistent performance during long-running AI tasks.
Hardware capabilities mean little without software support. NVIDIA cards currently offer the most mature ecosystem for AI frameworks like PyTorch and TensorFlow. However, AMD and Intel are releasing optimized drivers for Linux inference. Check if your preferred AI tools explicitly support the card architecture before purchasing.
Prioritize cards with stable drivers for your operating system. Verify compatibility with your specific Python environment to avoid costly debugging issues later.
For very large models, scaling across multiple cards can help. Workstation GPUs are often optimized for NVLink or direct PCIe peer-to-peer communication. Consumer cards may not support scaling as efficiently. If you plan to build a cluster, choose cards with professional features and compatible cooling for rack mounting.
Consider multi-GPU support if you plan to cluster resources later. Look for cards with robust PCIe connectivity and driver support for multi-device operations.
High-end GPUs for AI can be expensive. Determine if a mid-range card with high VRAM offers better value than a top-tier card with less memory. Sometimes two cheaper cards provide better total capacity than one expensive flagship. Balance raw performance with total usable VRAM for your specific workflow.
Calculate value based on dollars per GB of VRAM. Often, larger capacity cards at mid-range price points provide better utility for local AI models.
Install the latest drivers from the manufacturer to ensure maximum compatibility with AI frameworks. Verify that your operating system kernel supports PCIe 5.0 and modern memory management features.
Configure your power supply to handle sustained peak loads. Use monitoring software to track temperatures and clock speeds during initial testing to ensure stability.
For multi-GPU setups, ensure proper airflow in your case to prevent heat buildup. Regularly clean dust from heatsinks and fans to maintain optimal cooling efficiency over time.
For basic inference on smaller models like 7B parameters, 8GB is the minimum. However, 16GB is recommended for comfortable usage. Larger models or fine-tuning tasks require 24GB or more to avoid running out of memory during processing.
NVIDIA currently offers superior software maturity and optimization for AI frameworks. While AMD hardware is competitive, its drivers are still catching up in ecosystem support. Most developers recommend NVIDIA for reliability.
Yes, consumer gaming GPUs are often used for local training and inference. However, they lack ECC memory and multi-GPU scaling features found in professional cards. For small-scale projects, gaming GPUs are often sufficient.
AI training involves massive data transfer between the CPU and GPU. PCIe 5.0 doubles the bandwidth of previous generations, significantly reducing bottlenecks during data loading. This leads to faster overall training and inference times.
High-end AI GPUs can draw between 250W and 600W under full load. Ensure your power supply has adequate wattage and the correct connectors. Efficient cooling is also crucial to manage the heat generated during sustained usage.
For most hobbyists, a gaming card with high VRAM is enough. Workstation GPUs provide stability, ECC memory, and certified drivers for enterprise reliability. If you run critical daily workloads, workstation cards are worth the extra investment.
We reviewed ten top GPUs ranging from consumer gaming cards to high-end workstation accelerators. Each offers distinct advantages for different user needs, from budget-friendly inference to enterprise-grade deployment.
Prioritize memory capacity and bandwidth to ensure smooth performance for your chosen models. Always check driver compatibility before purchasing to avoid software headaches down the line.
Prices change frequently, so verify current listings before buying. The market for AI hardware evolves rapidly, and the best value today may shift as new models arrive.